Posted in Security Operations
America’s Infrastructure Is Sending a Warning. Are Boards Listening?
Victor Font — Keynote Speaker | Strategic Technology Leader | Fractional CIO | IT & Cyber Governance Expert | Published Author | FedRAMP Readiness | Board-Level Advisor | Digital Transformation | Enterprise WordPress/Formidable Forms
As intelligence networks falter, trusted software delivers malicious code, payment information is exposed, and autonomous cyberattacks accelerate, the question is no longer whether systems will fail. It is whether organizations can demonstrate that they are prepared.
On November 17, 2026, an unusual convergence of cybersecurity and infrastructure headlines raised an uncomfortable question about the resilience of America's digital systems.
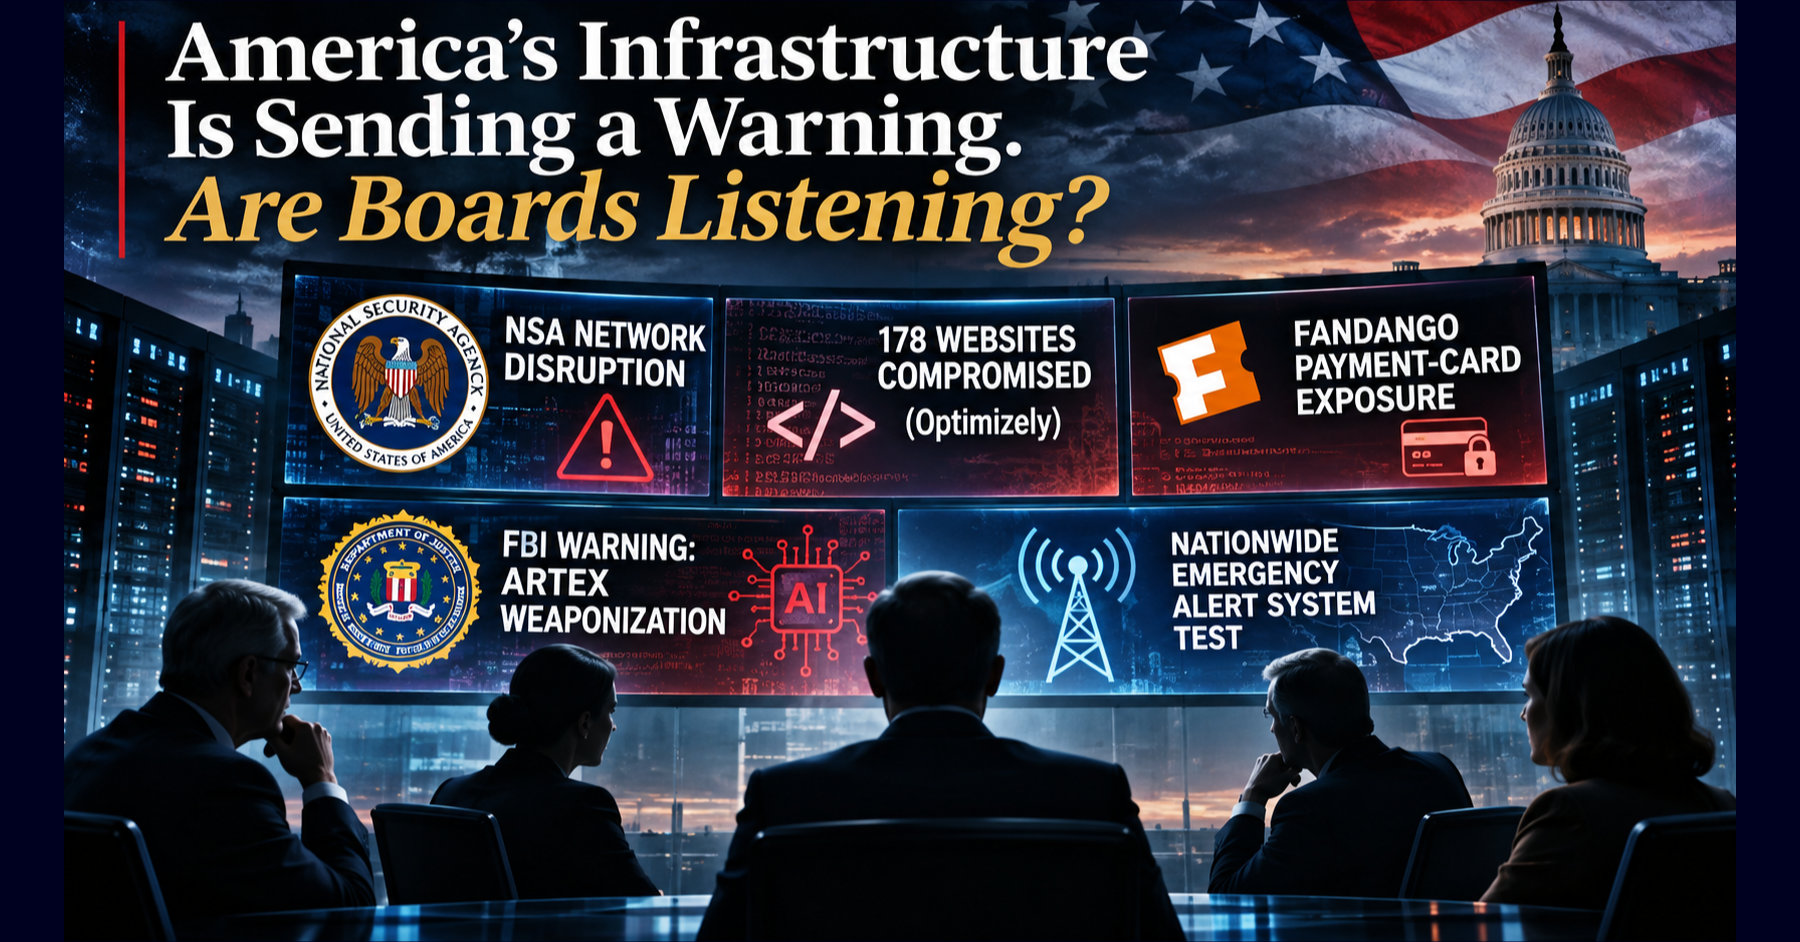
The National Security Agency experienced a disruption affecting its classified internal communications network.
Security researchers disclosed that malicious JavaScript had reached websites associated with at least 178 organizations through a compromised software dependency.
Fandango was notifying customers that payment card information may have been exposed through its online ticketing checkout page.
The FBI had just issued an advisory warning that malicious actors were weaponizing an autonomous penetration-testing framework capable of advancing cyber intrusions at machine speed.
And on that same Tuesday, the federal government conducted a nationwide test of the Emergency Alert System.
These developments followed other high-profile technology disruptions involving aviation, banking, and commercial cloud services.
It was an extraordinary collection of headlines.
The timing naturally invites speculation. Were these incidents connected? Was the emergency communications test related to a broader national security concern? Was something happening beneath the surface that the public had not yet been told?
Those questions deserve disciplined examination, not premature conclusions.
There is no verified evidence establishing that these incidents were coordinated. Several involved different technologies, occurred on different dates, and had different reported causes. The nationwide emergency communications test had been publicly scheduled two months earlier.
But dismissing their collective significance because they are not demonstrably connected would miss a more important issue.
The common warning is not that America is necessarily experiencing a coordinated cyberattack. It is that modern institutions have become extraordinarily dependent upon interconnected systems whose failure can have consequences far beyond the technology itself.
That is a governance problem.
And it belongs in the boardroom.
When the Nation's Intelligence Network Experiences a Disruption
On November 17, reports emerged that NSA Net, the National Security Agency's classified internal communications network, had experienced a significant operational disruption.
The network supports the storage, exchange, and communication of classified information within one of America's most sensitive intelligence organizations.
According to CBS News, some personnel at Fort Meade were instructed to stagger their arrival times to reduce simultaneous network logins. Reporting also described disruptions to normal workflows.
The NSA subsequently confirmed that it had experienced temporary service degradation during scheduled routine maintenance.
The agency emphasized that mission-critical capabilities remained operational and that its infrastructure incorporated multiple layers of redundancy.
That statement is important.
A technology disruption does not necessarily constitute a mission failure. An organization with effective continuity capabilities may sustain essential operations even when supporting infrastructure becomes unavailable.
Indeed, that is precisely what operational resilience is supposed to accomplish.
Nevertheless, the incident raises questions that apply far beyond the intelligence community.
How are risks evaluated before maintenance changes are authorized?
What dependencies must be identified before changes are introduced into critical systems?
Are rollback procedures tested against realistic failure scenarios?
Can operations continue without relying upon the affected infrastructure?
And what evidence demonstrates that continuity mechanisms performed as designed?
The answers cannot be found in a maintenance schedule or a disaster recovery policy alone.
They require demonstrable assurance that technical controls, operational procedures, and decision authorities work together under degraded conditions.
Resilience is not the absence of disruption. It is the ability to sustain essential operations despite disruption.
For boards overseeing critical infrastructure, financial institutions, healthcare organizations, and other technology-dependent enterprises, that distinction is fundamental.
One Trusted Software Dependency. At Least 178 Organizations Exposed.
While the NSA disruption attracted national security attention, another incident demonstrated how a single trusted software service can expose numerous organizations simultaneously.
On November 16, security researcher Scott Helme of Report URI identified malicious JavaScript being delivered through Optimizely, a platform used by organizations to personalize websites and conduct digital experiments.
Researchers examined 1,611 Optimizely scripts and identified 188 infected scripts associated with 178 organizations.
The affected websites included prominent names in financial services, technology, media, retail, telecommunications, and other industries.
Among those identified were the BBC, CNN, Zoom, Salesforce, GitLab, Equifax, and IKEA.
The malicious code was delivered through legitimate Optimizely infrastructure.
That detail is central to understanding the governance failure mode.
The attackers did not need to compromise the internal networks of 178 organizations individually.
Instead, they exploited a vulnerability in a shared software platform and inserted malicious code into customer projects.
The affected websites then delivered that code to visitors through a previously trusted integration.
According to security researchers, the malicious payloads included capabilities associated with payment-card theft, cryptocurrency address substitution, and exploitation of vulnerable devices.
Optimizely confirmed the incident and reported that it had corrected the vulnerability, removed the injected code, and taken steps to secure affected accounts.
The 178 organizations represent identified exposure through compromised scripts, not 178 confirmed corporate network breaches. The number of visitors whose information was actually stolen remains uncertain.
But the architectural implications are unmistakable.
Organizations routinely incorporate third-party JavaScript into customer-facing applications.
Analytics platforms, advertising systems, experimentation tools, payment integrations, and other external services execute code within environments customers associate with the organization's own brand.
Each integration creates a relationship of operational trust.
And each relationship potentially extends the organization's attack surface.
A vendor security assessment completed months earlier cannot establish that a script executing today remains trustworthy.
A contractual obligation cannot prevent malicious code from reaching a customer's browser.
And a favorable compliance report cannot substitute for technical controls that continuously verify what external software is doing.
Third-party risk does not end when the vendor is approved. It continues every time the dependency executes.
This incident illustrates why software supply-chain governance must extend beyond procurement, contracts, and annual assessments.
Boards should expect management to understand which external components can execute code, what privileges those components possess, how unauthorized changes are detected, and what mechanisms exist to restrict or disable compromised dependencies.
Without those capabilities, organizations may be trusting software they cannot effectively govern.
Fandango: When the Checkout Page Becomes the Attack Surface
The Optimizely compromise was not the only recent incident involving the integrity of customer-facing websites.
Fandango, the online movie ticketing platform, disclosed a security incident involving its checkout page.
According to a breach notification filed with the California Attorney General, an unauthorized party could access payment card information associated with certain transactions between October 8 and October 11, 2026.
The potentially exposed information included payment card numbers, expiration dates, CVV security codes, billing ZIP codes, and customer email addresses.
Fandango determined on October 30 that customer information may have been affected and subsequently began notifying impacted individuals.
The company reported that it had resolved the issue and strengthened its security protections.
The public notification does not establish the precise technical mechanism by which the unauthorized access occurred. Reports have characterized the incident as payment-page skimming, but the available disclosure does not establish whether a compromised third-party script was responsible.
There is also no verified evidence connecting the Fandango incident to the Optimizely compromise.
Nevertheless, the incidents illustrate related risks.
Customers see a trusted website and assume that information entered into its payment forms is being handled securely.
They generally cannot distinguish between code developed by the merchant, code supplied by a payment processor, and functionality delivered by other external services.
Nor should customers be expected to understand those distinctions.
The organization accepting the transaction bears responsibility for establishing appropriate safeguards.
That responsibility has a direct regulatory and technical dimension.
PCI DSS 4.0.1 includes requirements addressing payment-page script authorization, integrity assurance, script inventories, and mechanisms for detecting unauthorized changes to payment pages.
These controls reflect a fundamental reality: protecting the payment processing infrastructure is not sufficient if malicious code can intercept information before it reaches that infrastructure.
The governance issue extends beyond compliance.
Who authorizes code to execute on sensitive transaction pages?
Who verifies that the code remains unchanged?
How quickly can unauthorized modifications be detected?
Who has authority to disable a compromised integration?
And can the organization reconstruct which customers may have been exposed during the incident window?
A secure payment environment is not merely one that passed its last assessment. It is one whose integrity can be continuously demonstrated.
That principle should apply to every digital interaction involving sensitive customer information.
The FBI Warns That Attackers Are Moving at Machine Speed
On November 13, the FBI issued FLASH advisory FLASH-20261113-001, titled Threat Overview of ARTEX Autonomous Penetration Testing Framework .
The advisory described how malicious actors were weaponizing ARTEX, an open-source, large language model-driven agentic framework originally designed for autonomous penetration testing.
According to the FBI, attackers have used the framework to automate multiple stages of cyber intrusions, including reconnaissance, exploitation, privilege escalation, and data exfiltration.
The advisory described campaigns targeting organizations across financial services, government, defense, technology, healthcare, telecommunications, manufacturing, energy, and other sectors.
Some reported intrusions progressed from initial targeting to privileged access in less than three hours.
That timeframe deserves particular attention from boards and executive leadership.
Cybersecurity governance has traditionally assumed that meaningful decisions can pass through established human approval processes.
An alert is detected.
An analyst investigates.
A manager evaluates the potential impact.
An incident commander determines the appropriate response.
Business leadership approves disruptive containment measures.
The security team executes the intervention.
Each step may be reasonable when examined independently.
But what happens when an attacker can reach privileged access before that approval sequence is completed?
What happens when the attack progresses faster than the organization can authorize its response?
The emergence of increasingly autonomous offensive capabilities exposes a potential mismatch between technical attack velocity and organizational decision velocity.
This does not mean that organizations should surrender cybersecurity decisions to autonomous defensive systems without oversight.
It means governance must establish decision rights before the emergency occurs.
In emergency medical services, standing orders allow qualified personnel to perform specified interventions when predefined clinical conditions are present.
The authorization exists before the emergency.
The intervention remains bounded by professional standards, defined protocols, and documentation requirements.
Cybersecurity can apply a comparable principle.
Organizations can preauthorize specific defensive actions under carefully defined conditions.
A compromised endpoint might be isolated automatically.
A suspicious session might be revoked.
A malicious process might be terminated.
A high-confidence indicator might trigger temporary restrictions on access.
More consequential actions could still require human authorization.
The objective is not unrestricted automation.
It is a governed decision architecture that distinguishes actions safe to execute immediately from those requiring additional judgment.
Such an architecture should define triggers, limits, escalation requirements, verification procedures, and evidence capture.
Human accountability must remain intact even when human approval cannot remain in the critical path of every defensive action.
The FBI's warning makes that distinction increasingly urgent.
Then America Tested Its Emergency Communications System
On November 17, FEMA and the Federal Communications Commission conducted their previously announced nationwide Emergency Alert System test.
The test was scheduled publicly on September 16, approximately two months before the week's infrastructure disruptions.
It was not an emergency activation hastily arranged in response to the NSA outage or the other incidents.
That distinction is essential.
But the timing provided an opportunity to consider a larger question about national resilience.
How dependable are emergency communications when the broader infrastructure environment is experiencing serious disruption?
The Emergency Alert System enables authorized emergency information to reach the public through participating broadcasters and communications providers.
Its effectiveness depends upon more than the initial transmission of an alert.
Messages must be generated and authenticated.
Distribution systems must deliver them.
Participating communications providers must receive and process them.
Supporting infrastructure must remain available.
And alternative distribution mechanisms must function when individual components fail.
The nationwide test was designed to assess aspects of that capability under controlled conditions.
Its actual performance should be evaluated using FEMA's published test results and subsequent analysis rather than assumptions based upon the day's other headlines.
The broader governance question remains important.
An emergency communications architecture can include redundant components while retaining shared dependencies that create common failure domains.
Multiple distribution paths may rely upon the same telecommunications infrastructure.
Separate systems may depend upon common authentication, routing, power, or management services.
Operational procedures may depend upon personnel who cannot reach their facilities during a regional emergency.
The existence of redundancy does not automatically establish independence.
A system is not resilient simply because it has a backup. It is resilient when the backup can perform the required mission under the conditions that caused the primary system to fail.
That distinction applies equally to national emergency communications and enterprise business continuity.
The Warning Is Not Coordination. It Is Dependency.
The NSA disruption, Optimizely compromise, Fandango incident, ARTEX warning, and emergency communications test involved different circumstances.
They should not be represented as evidence of a single coordinated attack.
The NSA attributed its disruption to scheduled maintenance.
Optimizely confirmed exploitation of a vulnerability in its web experimentation platform.
Fandango disclosed unauthorized access to payment information through its checkout environment.
The FBI described a broader pattern of malicious actors adopting autonomous offensive capabilities.
The Emergency Alert System test was planned well in advance.
These are distinct developments.
Yet their collective significance lies in the dependencies they expose.
Modern enterprises rarely operate as self-contained technology environments.
Their essential functions depend upon cloud providers, telecommunications networks, identity platforms, software vendors, managed service providers, payment processors, and external data services.
Those dependencies are often layered.
A customer-facing application may depend upon an external authentication provider, which depends upon a cloud platform, which depends upon telecommunications services, which depend upon shared infrastructure.
An organization may maintain redundant application servers while relying upon a single identity service.
It may operate geographically separated data centers while depending upon a common management plane.
It may maintain multiple network connections that ultimately traverse the same physical route.
It may have an incident response plan that requires authorization from someone unavailable during the crisis.
And it may depend upon a trusted software component whose behavior can change without the organization's direct approval.
The traditional approach to resilience often concentrates on individual systems.
But protecting individual systems does not necessarily preserve an end-to-end business capability.
Boards must therefore move beyond asking whether critical applications have backups.
They should ask whether the organization understands the complete dependency architecture supporting its essential operations.
That includes the technology, the suppliers, the people, the decision authorities, and the evidence required to demonstrate effective control.
Five Questions Every Board Should Ask
The recent incidents offer an opportunity for boards to examine whether their organizations are governing operational resilience or merely receiving reports about it.
1. Which business capabilities must remain operational when supporting systems fail?
Criticality should be defined in terms of business and mission outcomes.
Server availability is not the same as business continuity.
A technically available application may be operationally useless if its authentication service, payment processor, telecommunications connection, or required data source is unavailable.
Boards should understand which outcomes must be preserved and the maximum tolerable disruption for each.
2. Where do apparently independent systems share hidden dependencies?
Redundancy is meaningful only when alternative components do not fail from the same underlying cause.
Management should identify common failure domains involving cloud platforms, networks, identity providers, suppliers, control planes, and operational personnel.
Resilience testing should validate those assumptions.
3. Who has authority to act when an incident develops faster than normal approval processes can accommodate?
Machine-speed attacks require organizations to distinguish between decisions that can be safely preauthorized and those requiring human judgment.
Boards should expect clearly documented intervention thresholds, delegated authorities, escalation paths, and safeguards against excessive or inappropriate automated actions.
The existence of an incident response plan does not establish that the organization can execute it quickly enough.
4. How does the organization continuously verify the integrity of third-party software?
The Optimizely and Fandango incidents demonstrate why customer-facing applications deserve particular scrutiny.
Management should understand which external scripts and services execute within sensitive environments, how those components are authorized, and what controls detect unauthorized modifications.
Supplier due diligence must be complemented by operational verification.
5. What evidence demonstrates that resilience controls actually work?
This may be the most consequential question.
Boards should expect more than policies, architecture diagrams, recovery objectives, and management assurances.
They should receive evidence of actual exercises, recovery performance, dependency testing, change validation, containment execution, and remediation verification.
The organization should be able to demonstrate that its resilience mechanisms work under realistic conditions.
Not simply that they exist.
Resilience Without Evidence Is an Assumption
Organizations invest substantial resources in disaster recovery, business continuity, cybersecurity monitoring, incident response, and third-party risk management.
Yet many still struggle to demonstrate how governance decisions translate into operational outcomes.
Consider the questions that follow a serious infrastructure disruption.
Who authorized the change?
What risks were identified beforehand?
Which dependencies were evaluated?
Were rollback procedures validated?
What triggered containment?
Who possessed authority to intervene?
How long did intervention take?
Did the backup systems perform as expected?
Were recovery objectives achieved?
Who verified that the underlying risk had been addressed?
And what evidence supports the answers?
If the organization must reconstruct those facts from disconnected logs, email messages, meeting notes, tickets, and individual recollections, it has an evidentiary weakness.
This is the problem addressed by Evidentiary Architecture™.
The concept establishes that governance decisions, delegated authorities, control execution, operational outcomes, and verification records should be connected through a deliberate evidence architecture.
Rather than treating evidence as something assembled for auditors after an event, organizations should design their governance and operational processes to produce trustworthy evidence as decisions and actions occur.
A maintenance change should produce an identifiable authorization record, documented risk evaluation, validation results, and operational outcome.
An automated containment action should produce evidence of the triggering condition, the authority under which it operated, the intervention performed, and the subsequent verification.
A third-party software change should be traceable to an approved dependency, authorized execution boundary, and integrity control.
A recovery exercise should demonstrate not merely that systems restarted, but that the required business capability was restored within approved tolerances.
These records should be sufficiently reliable, attributable, and connected to support independent examination.
The objective is not simply compliance readiness.
It is defensibility.
An organization should be able to demonstrate that its governance mechanisms operated as intended—not merely assert that appropriate policies were in place.
That distinction becomes increasingly important as digital dependencies multiply and operational decision windows shrink.
The Boardroom Takeaway
The events surrounding November 17 do not establish that America is experiencing a coordinated cyber campaign against its critical infrastructure.
They do reveal an increasingly demanding environment for organizations responsible for essential digital services.
Routine maintenance can disrupt sensitive internal networks.
A trusted software platform can become a distribution mechanism for malicious code across numerous organizations.
A customer-facing checkout page can expose payment information.
Autonomous offensive frameworks can accelerate intrusions beyond traditional human response timelines.
And national emergency communications capabilities must remain dependable under conditions that may be far more challenging than a scheduled test.
These are not merely technology concerns.
They are questions of enterprise governance, operational accountability, and institutional resilience.
Boards cannot eliminate every failure.
They cannot personally evaluate every software dependency or approve every defensive intervention.
But they can require management to establish an architecture of accountability that makes critical dependencies visible, assigns appropriate decision authority, validates continuity mechanisms, continuously verifies essential controls, and produces evidence of operational effectiveness.
The responsibility is not to guarantee that nothing will ever go wrong.
It is to ensure that the organization can sustain its essential mission when something does.
The question is no longer whether critical systems will experience disruption.
The question is whether leadership can demonstrate that the organization was prepared to sustain its mission when they do.
#CybersecurityGovernance #CriticalInfrastructure #CyberResilience #SupplyChainSecurity #ThirdPartyRisk #AICybersecurity #ExecutiveAccountability #OperationalResilience
1 reactions · 0 comments
Topics: #thirdpartyrisk, #cybersecuritygovernance, #executiveaccountability, #supplychainsecurity, #aicybersecurity, #criticalinfrastructure, #operationalresilience, #cyberresilience